
How to Clean Video Audio Before Transcription
For better transcription, preserve the original, isolate the speech channel, remove only noise that masks words, normalize sections conservatively, and submi
For better transcription, preserve the original, isolate the speech channel, remove only noise that masks words, normalize sections conservatively, and submit a clean constant-format file. Validate improvement with a short transcript test instead of assuming a nicer waveform means better recognition.
The practical goal is not to make one processing screen look successful. It is to preserve the viewer’s ability to understand the intended message after editing, encoding, platform upload, and localization. This guide treats the task as a controlled workflow: diagnose first, make the least destructive change, and validate the actual deliverable.
Start With the Viewer’s Failure
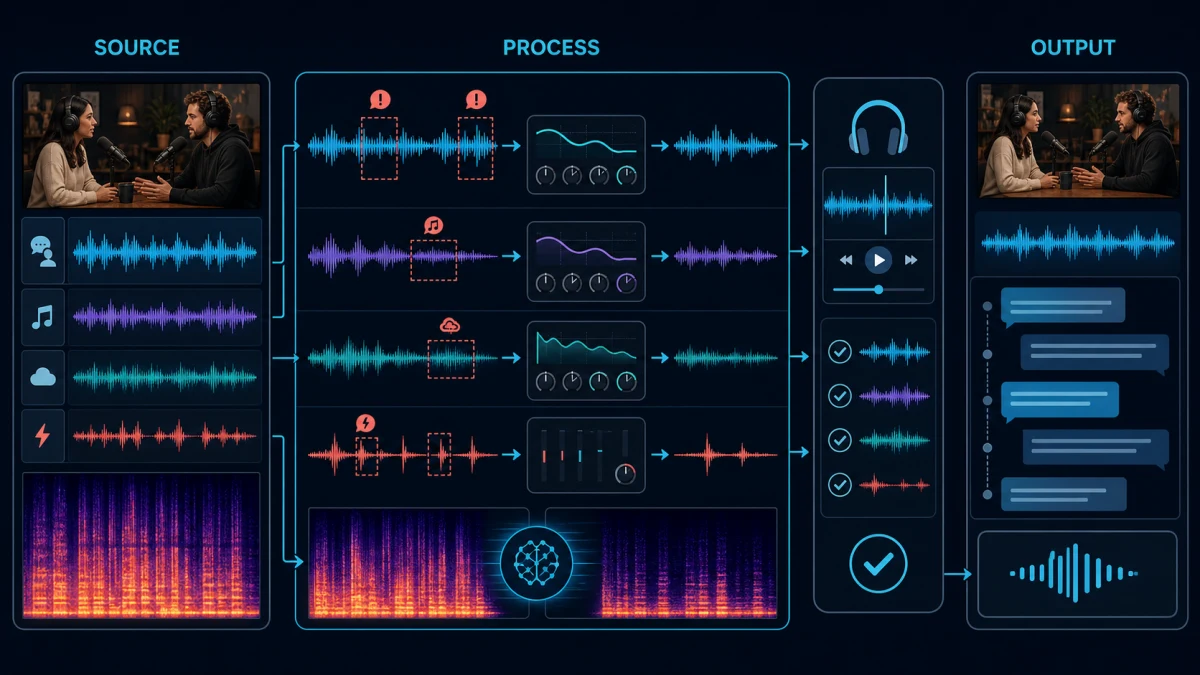
People usually describe a production symptom—“the subtitles look wrong,” “the voice sounds off,” or “the audio is bad”—but that description is not yet a diagnosis. Ask what the viewer cannot do. Can they not read the line, identify the speaker, hear a word, follow the sequence, trust the performance, or act on the CTA? The answer determines which evidence matters.
- Check channel routing: speech may be clean in one channel and contaminated in another.
- Identify clipping, missing speech, cross-talk, music, reverberation, and steady noise separately.
- Record names, acronyms, domain terms, and speaker identities that automated transcription is likely to miss.
Create a short issue log with timecode, symptom, likely cause, severity, owner, and acceptance test. This is faster than passing subjective notes such as “make it cleaner” among editors, translators, and reviewers.
Decide What Good Looks Like
Use explicit release criteria before you touch the file.
| Gate | Question | Evidence |
|---|---|---|
| Meaning | Are facts, names, numbers, negation, conditions, and intent preserved? | Source comparison and native or subject-matter review |
| Perception | Can a first-time viewer understand the important moment once? | Fresh-listener or fresh-viewer test |
| Technical | Does the output retain sync, encoding, channels, fonts, and required format? | File inspection and final-render playback |
| Continuity | Do edited sections belong to the same program? | A/B review across transitions |
| Delivery | Does the destination platform display and play it correctly? | Private upload or representative device test |
| Repeatability | Can another operator reproduce the approved result? | Versioned settings, glossary, or decision log |
A quality gate should include a stop condition. If key words remain unintelligible, if protected meaning changes, if direction or timing breaks, or if processing artifacts attract attention, do not keep adding aggressive corrections. Escalate to a different method or replacement.
Full Workflow
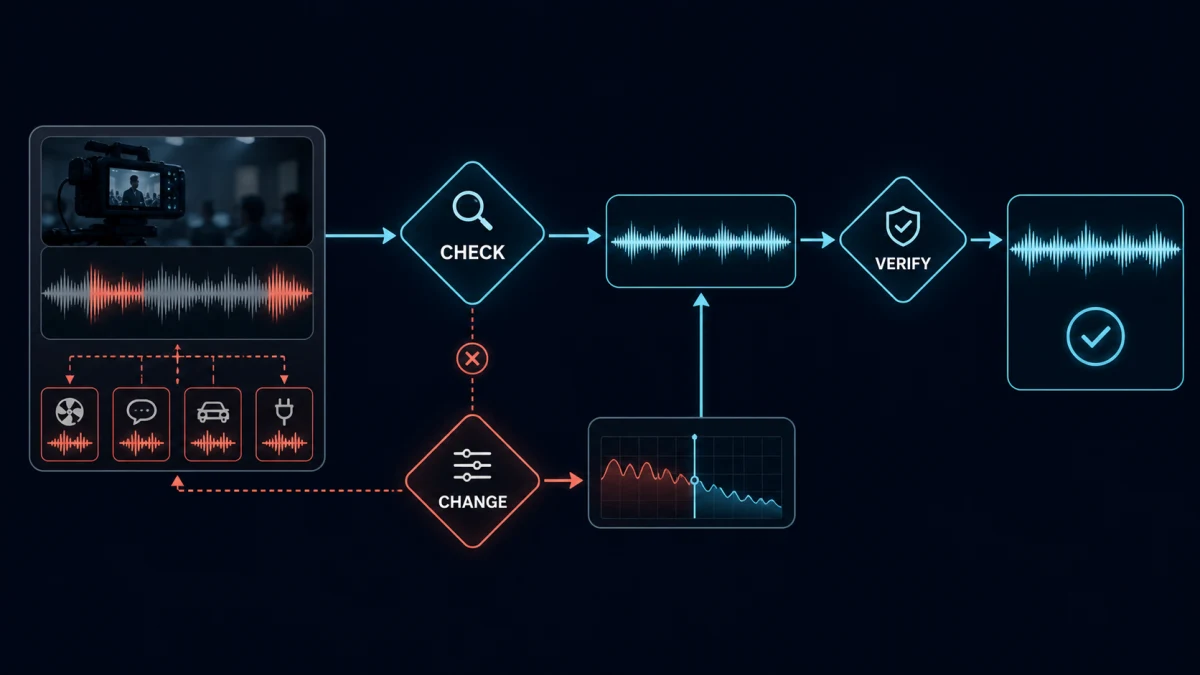
1. Lock the final edit and preserve sync
Transcribe the final or near-final picture. Keep an untouched master and do not introduce trims that break timecode after subtitles are built.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
2. Select the best speech source
Choose the lavalier, boom, recorder, or channel with the highest intelligibility. Do not automatically mix every microphone, because phase and room noise can become worse.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
3. Remove non-speech sections strategically
Trim long silence, slates, and irrelevant music only when timecode requirements allow. Keep speaker turns and context needed for labeling.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
4. Reduce masking, not every trace of ambience
Use light denoising for steady hiss or hum and isolation for overlapping music. Stop before consonants become smeared or synthetic.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
5. Correct extreme level differences
Bring very quiet speakers into a workable range without crushing dynamics. Split problem sections rather than applying one aggressive setting to the entire file.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
6. Export a stable transcription copy
Use a common uncompressed or high-quality format, consistent sample rate, and clear channel layout. Name the file with source version and edit date.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
7. Run a benchmark transcript
Transcribe the same representative minute before and after cleanup. Compare names, negation, numbers, turn boundaries, and missing words—not only overall readability.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
8. Human-correct against picture
Verify the machine transcript while watching the final video. Correct terminology and speaker labels, then generate subtitle timings from the corrected source.
Do not approve this stage from an interface message alone. Compare the result with the preserved source, inspect the most difficult segment, and record the setting or decision that produced the accepted version. If this stage changes timing, wording, channels, or visible text, flag every downstream asset that must be regenerated.
Worked Example
A panel recording has the moderator on the left channel, guests on the right, and music in the opening. A mono mix buries the moderator. The editor extracts both channels, balances the speech segments, removes the opening music from the transcription copy, lightly reduces HVAC hum, and tests one minute containing interruptions. The cleaner copy improves speaker turns, but a human still corrects product names and overlapping speech.
This example illustrates a wider rule: solve the highest-impact constraint first, then reassess. Processing order matters because every stage changes the evidence available to the next one. A workflow that jumps straight to export can hide the cause and make later corrections expensive.
How to Judge the Result Objectively
Use a three-pass review.
Pass 1: technical isolation
Inspect the exact defect on a short, repeatable segment. Keep settings stable, compare against the original, and avoid changing multiple variables. For audio, level-match before listening. For subtitles or graphics, use the same frame, scale, and renderer.
Pass 2: narrative and task context
Watch at least the full scene before and after the corrected moment. Verify that the line, sound, or graphic still performs its job. A local edit may be technically clean but remove a joke, soften a warning, hide a product demonstration, or create an unnatural transition.
Pass 3: final delivery
Review the encoded deliverable from beginning to end. Test representative devices and the destination platform when possible. Verify the first seconds, the most difficult section, transitions, and the ending. Random spot checks are useful only in addition to these known risk points.
Track defects by severity:
- Blocker: wrong language, missing media, changed fact, rights problem, broken sync, unreadable text, or unintelligible required speech.
- Major: repeated terminology error, obvious artifact, inconsistent tone, distracting level jump, or failed CTA.
- Minor: isolated cosmetic issue that does not change comprehension.
- Preference: stylistic alternative that does not violate the brief.
Do not let a long list of preferences obscure one blocker.
Where the Related Workflows Fit
If the defect is upstream, start with the related workflow to choose between voice isolation and noise reduction. That prevents polishing a symptom while the source problem remains.
When the first pass is stable, repair masking before changing loudness provides the next operational layer. Use it only where the current diagnosis shows that extra treatment is needed.
Before delivery, extract a dedicated transcription file without losing sync. This handoff matters because a technically correct intermediate file can still fail in context.
Finally, verify the final mix before publication so the decision is validated in the complete publishing workflow.
These links represent handoffs, not a requirement to use every tool. Keep the workflow proportional. If the source is already clear and valid, additional processing can create more risk than value.
How Recapo Fits the Process
Recapo’s current relevant production tool can accelerate the central processing step in this workflow. Use it on a copy of the source, begin with a representative sample, and save the output with a versioned name. Automation is most valuable when it produces a reviewable candidate quickly.
It does not replace:
- source-version control;
- native-language or subject-matter judgment;
- rights and consent review;
- an acceptance test tied to the viewer’s task;
- inspection of the final encoded file; or
- a human decision when the source information was never captured.
For a repeatable team process, store the source, tool output, settings or prompts, human corrections, approval status, and final export together. That record prevents the next project from repeating the same diagnosis.
Common Failure Modes and Recovery
Mixing all available microphones without checking phase or noise.
Why it fails: the workflow optimizes one visible symptom while leaving meaning, timing, intelligibility, or delivery behavior untested.
Correction: return to the smallest representative sample, change one variable, compare at matched conditions, and accept the result only after it survives the final context.
Applying heavy denoising that erases consonants needed by speech recognition.
Why it fails: the workflow optimizes one visible symptom while leaving meaning, timing, intelligibility, or delivery behavior untested.
Correction: return to the smallest representative sample, change one variable, compare at matched conditions, and accept the result only after it survives the final context.
Normalizing clipped audio and expecting lost words to return.
Why it fails: the workflow optimizes one visible symptom while leaving meaning, timing, intelligibility, or delivery behavior untested.
Correction: return to the smallest representative sample, change one variable, compare at matched conditions, and accept the result only after it survives the final context.
Generating captions before the picture edit is locked.
Why it fails: the workflow optimizes one visible symptom while leaving meaning, timing, intelligibility, or delivery behavior untested.
Correction: return to the smallest representative sample, change one variable, compare at matched conditions, and accept the result only after it survives the final context.
Measuring success by waveform appearance instead of transcript errors.
Why it fails: the workflow optimizes one visible symptom while leaving meaning, timing, intelligibility, or delivery behavior untested.
Correction: return to the smallest representative sample, change one variable, compare at matched conditions, and accept the result only after it survives the final context.
A Practical Team Handoff
A useful handoff package contains:
- source filename and checksum or version;
- exact timecodes in scope;
- target language, market, platform, and aspect ratio where relevant;
- approved transcript, glossary, pronunciation, or audio reference;
- processing method and settings;
- known limitations and intentionally accepted residue;
- before-and-after sample;
- final acceptance criteria;
- reviewer name and review date; and
- final export plus editable source.
For high-volume work, review every first item in a new format or language, then sample routine items and inspect every flagged exception. Sampling is safe only after the process is stable and blockers have an escalation route.
Final Checklist
Before approval, confirm:
- the correct source and destination version were used;
- the original remains preserved;
- the problem was classified before treatment;
- protected meaning, names, numbers, and timing remain correct;
- settings were tested on both difficult and clean sections;
- no new artifact is more distracting than the original defect;
- transitions and continuity are natural;
- captions, voice, graphics, and picture remain aligned;
- the final encoded file was reviewed;
- representative device or platform behavior was tested;
- rights, disclosures, and accessibility needs were checked; and
- the decision and reusable settings were documented.
Frequently Asked Questions
Should I use the strongest automatic setting?
Usually no. Stronger processing can remove useful speech detail, natural ambience, typographic structure, or performance nuance. Start with the least destructive change that passes the acceptance test.
Can I approve from a waveform, transcript, or preview?
No single representation proves quality. A waveform cannot show meaning, a transcript cannot prove timing, and an editor preview cannot prove platform behavior. Review the finished audiovisual result.
Should every language or recording use identical settings?
Use the same quality gates, not necessarily identical settings. Languages differ in syntax, direction, duration, and performance. Recordings differ in room, microphone, noise, and dynamics.
What if the source is genuinely unrecoverable?
Do not invent missing information or hide the limitation. Re-record, replace, return to an original source, revise the edit, or disclose the uncertainty. A clean-looking output cannot restore content that was never captured.
How do I scale the workflow?
Stabilize one representative item, document decisions, create reusable glossaries or presets, and maintain an exception queue. Automate candidate generation and mechanical checks while keeping human review on meaning, naturalness, and release risk.
Conclusion
For better transcription, preserve the original, isolate the speech channel, remove only noise that masks words, normalize sections conservatively, and submit a clean constant-format file. Validate improvement with a short transcript test instead of assuming a nicer waveform means better recognition.
The reliable pattern is simple: preserve the source, diagnose the viewer-facing failure, test a small representative segment, make the least destructive correction, and approve only the final deliverable. That sequence produces better quality and a process the team can repeat.
References
- Recapo How to Clean Video Audio Before Transcription, accessed August 26, 2026.
- Internal workflow references linked above, prepared for the same Recapo editorial batch.